Bitwise-Deterministic Pretraining at Scale: How Megatron Core Finds and Removes Every Flipped Bit
Reading notes on:
A pretraining run on thousands of GPUs does trillions of floating-point reductions per step, and the order of many of them is decided by whoever finishes first: an atomic add, an autotuner’s pick, a collective’s arrival order. Floating-point addition is not associative, so each of these choices can flip a low-order bit. One flipped bit in a gradient becomes a different weight, a different router decision, and eventually a different loss curve. At trillion-parameter scale that makes a loss spike impossible to replay, a resumed checkpoint subtly different from the run it came from, and an A/B test between two library versions hard to read.
The NVIDIA post describes how Megatron Core reaches bitwise determinism for large hybrid pretraining recipes. It covers what “deterministic” has to mean to be useful, a tracing workflow (Megatron-LM PR #7262) that localizes the first divergent bit down to a kernel, a catalog of root causes, and kernel redesigns that bring the cost of determinism down to about 2% of step time, verified at 2,432 GPUs over 800 steps.
1. Two Guarantees
The post pins “deterministic” to two concrete, testable properties:
- Independent reproducibility. Two separate runs launched from the same initial state produce bitwise-identical parameter trajectories at every iteration.
- Bitwise checkpoint resume. A run that is interrupted, checkpointed, and restored continues along exactly the same numerical trajectory as an uninterrupted reference run.
The second is strictly harder than it looks. It requires the checkpoint to capture everything that influences the next step, not just the weights.
2. Why It Is Worth Paying For
- Failure replay. A loss spike or crash at step $t$ can be reproduced exactly, so the root cause can be isolated by changing one variable at a time. Without determinism every replay is a slightly different run, and the spike may not recur.
- Checkpoint continuity. Resuming does not inject numerical noise or shift the optimization trajectory.
- Corruption detection. If two identical runs disagree, something is wrong: degrading hardware, silent data corruption, or a software regression. Determinism turns “noise” into a signal.
- Clean A/B tests. A library update or compiler change can be evaluated against a bitwise baseline, so any difference is a real algorithmic difference rather than run-to-run variance.
- Cost. On 10,000 GPUs over a 100-day run, cutting the determinism overhead from 15% to 5% saves roughly 10,000 × 100 × 10% = 100,000 GPU-days. That is why the tax, not just the property, is the headline.
This connects to the numerics theme in Training-Inference Parity in MoE Models and Rollout Routing Replay: in MoE models a tiny numerical perturbation can flip a top-k routing decision, so small nondeterminism gets amplified into a discrete change in which experts run.
3. Verifying Determinism: Printed Loss Is Not Evidence
Logged loss values are rounded to 4 to 6 decimal places. Two runs can print identical losses for thousands of steps while their gradients, weights, and optimizer states have already diverged in the low-order bits. Visible divergence often shows up long after the first flipped bit.
So verification uses full-precision fingerprints at every step:
\[\text{Metrics fingerprinted} = \{\, \text{training loss},\ \text{LM loss},\ \text{load-balancing loss},\ \text{MTP loss},\ \text{gradient norm} \,\}\]For bitwise checkpoint resume, the state before save and after restore is compared against an uninterrupted run, covering:
- parameter tensors $\mathbf{W}_t$
- optimizer states $\mathbf{m}_t$ and $\mathbf{v}_t$
- every pseudo-random number generator (RNG) state
- the data loader’s position in the sequence
For low-precision training (FP8, FP4), the checkpoint preserves a full-precision source of truth, and restore reconstructs the low-precision weights along exactly the same conversion path used during training. Rebuilding scales any other way gives “equivalent” weights that are not bitwise equal. The same full-precision-master idea runs through NVFP4 training, MXFP8 training, and the Nemotron 3 Ultra NVFP4 checkpoint.
4. Localizing the First Divergent Bit (PR #7262)
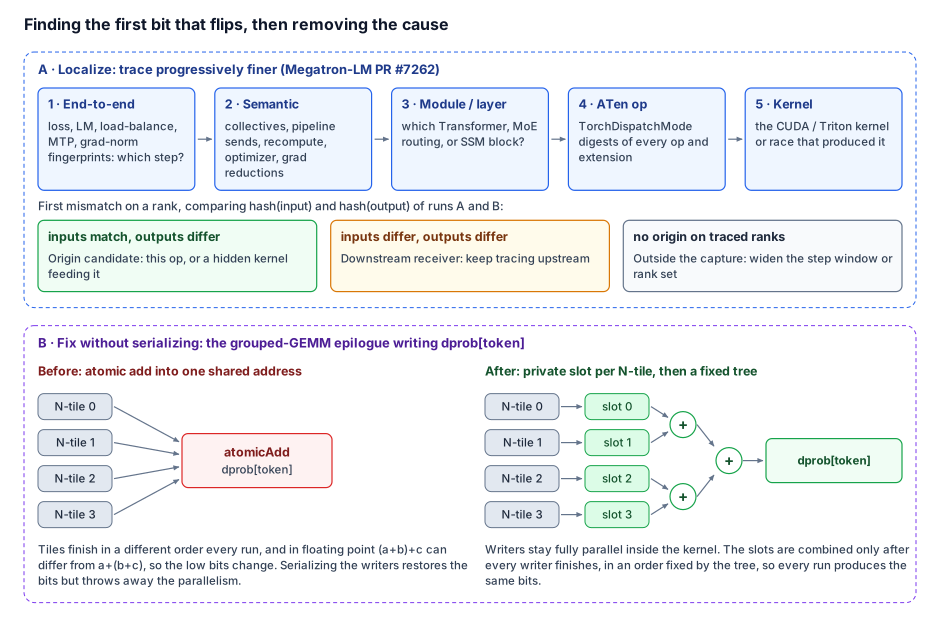
Divergence in real runs is often intermittent, topology-dependent, and noticed long after the origin. Megatron-LM PR #7262 adds an offline tensor-fingerprint comparison workflow that narrows the search one level at a time:
- End-to-end metrics find the exact iteration where divergence begins.
- Broad semantic tracing covers distributed collectives, pipeline communication, recomputation, optimizer states, and gradient reductions.
- Module and layer tracing narrows it to a specific Transformer block, MoE routing, or state-space model (SSM) block.
- Operation-level tracing fingerprints PyTorch ATen calls and custom extensions.
- Kernel-level tracing pinpoints the nondeterministic CUDA or Triton kernel, or race condition.
Trace without synchronizing
Each rank writes its own trace log to disk without any cross-rank collectives. That matters: adding a collective to the tracer would impose an ordering across ranks and could hide exactly the race you are looking for. Events from the two runs are aligned afterwards using run-independent identifiers: operation name, invocation count, and module scope.
Reading the first mismatch
For paired runs $A$ and $B$, the origin is the first event where
\[\text{hash}(\text{input}_A) = \text{hash}(\text{input}_B) \quad \text{and} \quad \text{hash}(\text{output}_A) \neq \text{hash}(\text{output}_B)\]| First mismatch pattern on a rank | Interpretation | Next action |
|---|---|---|
| Inputs match; outputs differ | Candidate origin of nondeterminism | Investigate that operation, or the hidden kernel that produced its input |
| Inputs differ; outputs differ | Downstream receiver of already-divergent data | Keep tracing upstream |
| No origin found on traced ranks | Origin is outside the capture scope | Widen the step window or trace more ranks |
5. Fingerprinting Tensors on the GPU
Digests are computed directly in GPU memory with torch.hash_tensor, and each record carries
A few cases need care:
- Micro-scaling formats (MXFP8, NVFP4). Hash both the packed values and the scale-factor buffers. Identical packed values with different scales are different tensors.
- Order-sensitive tensors such as MoE routing maps. An XOR-style whole-tensor hash cannot see a permutation, and a routing map where two tokens swap experts has the same multiset of entries. Order-dependent data is hashed along a dimension with the
dimargument (row-wise or chunk-wise). - Final confirmation is always a byte-level memory comparison. The hash narrows the search; the bytes settle it.
False alarms
- Dispatcher blind spots. Custom C++/CUDA kernels that bypass PyTorch’s
TorchDispatchModeare invisible to ATen tracing. If the first mismatch shows up at a trivial view or slice, the real culprit is an uncaptured custom kernel upstream. - Probe artifacts. Hashing uninitialized buffers, the destination of an async collective before it completes, or the target of a nonblocking copy produces mismatches that are artifacts of the probe, not the training run.
6. Root-Cause Catalog
| Observed symptom | Root cause | How to diagnose | Fix |
|---|---|---|---|
| Run diverges from step 1, inconsistently | Runtime autotuning picks different kernel algorithms | Compare selected execution configs across runs | Pin or cache validated deterministic configs |
| MoE runs diverge when auxiliary-loss fusion is on | Atomic floating-point reductions in nondeterministic order | Disable fusions selectively; trace the loss steps | Deterministic reduction tree, or disable the fusion |
| Resumed run gradually drifts from reference | Incomplete RNG state capture/restore | Compare RNG states right before and after restore | Save and restore every RNG stream bitwise |
| Divergence after a container/software update | Lower-level library (e.g. cuBLAS) kernel change | Bisect the software stack; extract a minimal kernel repro | Pin deterministic kernel paths |
| Weights mismatch right after load | Low-precision scales reconstructed differently | Compare weights and scaling metadata after load | Keep a full-precision source of truth and the exact reconstruction path |
| Passes at small GPU counts, fails at scale | Scale-dependent collectives or expert paths | Scale up systematically; trace selected ranks | Isolate and fix the scale-dependent operations |
The last row is the expensive one: a recipe validated on a few nodes is not evidence for 2,000+ GPUs, because collective algorithms and expert placement change with topology (see MoE Parallel Folding and Scalable Training of MoE Models with Megatron Core for how those paths shift with parallelism layout).
7. The Determinism Tax
Determinism usually costs speed: atomics get serialized and autotuning gets disabled. The post defines the overhead against the fastest supported nondeterministic recipe with the same batch size, parallelism, precision, software, and hardware:
\[\text{Determinism tax} = \left( \frac{\text{deterministic step time}}{\text{baseline step time}} - 1 \right) \times 100\%\]Comparing against the fastest baseline, not a convenient one, is what keeps the number honest.
Results on trillion-parameter hybrid Nemotron workloads
The case study is a hybrid Mamba SSM + Transformer family (the architecture covered in Deep Dive into Nemotron 3 Ultra):
| Workload | Tax before | Tax after | Notes |
|---|---|---|---|
| Nemotron 3 Ultra | ~17% | 2% | after buffer-fill optimizations; 1.5% at 3,072 GPUs |
| Hybrid Triton proxy | ~60% | 37%, then ~2% | 37% after restoring MoE-MLP fusion; later stabilized at ~2% |
| CuTeDSL weight-gradient track | not reported | ~3.6% | at 256 GPUs |
| End-to-end scale benchmark | not reported | ~2% steady state | 2,432 GPUs, bitwise deterministic over 800 continuous steps |
Kernel redesign: the grouped-GEMM epilogue
The clearest example is in the MoE grouped GEMM. In the epilogue, several $N$-tiles accumulate atomically into the same output address dprob[token]. Tiles arrive in a different order each run, and since $a + b + c$ and $c + b + a$ need not round the same way, the result varies in its low bits.
- Naive fix: serialize the tile writers. Deterministic, but it removes the parallelism and creates a latency bottleneck.
- Optimized fix: give each $N$-tile a private output slot. Writers stay fully parallel, and once all of them finish, the slots are combined by a fixed reduction tree. Same parallelism, fixed summation order, same bits every run (panel B of the figure above).
This is the general pattern for deterministic kernels: keep the parallel work, and move the order-sensitive part into a small, fixed-order reduction at the end. It is the same epilogue-centric thinking as in CODA: GEMM-Epilogue Programming, applied to correctness instead of fusion.
8. Keeping It Deterministic: Three-Tier CI
Determinism regresses silently whenever a kernel, recipe, or number format changes, so Megatron Core tests it at three levels:
- Recipe validation.
--deterministic-modeapplies the canonical environment configuration, turns on PyTorch’s deterministic algorithms, and rejects feature paths known to be nondeterministic instead of silently running them. - Kernel-level tests. Each kernel runs repeatedly with fixed inputs and RNG state, and outputs and gradient tensors are compared byte for byte.
- Module-level tests. Transformer layers, SSM blocks, and MoE modules are run across parallelism strategies and low-precision formats (including FP8 and NVFP4), confirming that full-precision training metrics stay bitwise identical.
Takeaways
- Define determinism as two testable properties: independent reproducibility and bitwise checkpoint resume. The second requires checkpointing RNG streams, the data loader position, and a full-precision source of truth for low-precision weights.
- Printed loss proves nothing. Verify with full-precision fingerprints every step and confirm with byte-level comparison.
- Localize, don’t guess. Trace from metrics down to kernels, log per rank without collectives, and look for the first op whose inputs match but outputs differ.
- Hash carefully. Include scale buffers for MXFP8/NVFP4, hash order-sensitive tensors per dimension, and watch for dispatcher blind spots and probe artifacts.
- The tax can be small. Measured against the fastest nondeterministic baseline, the cost came down to about 2% at 2,432 GPUs, largely through kernel redesigns like private slots plus a fixed reduction tree instead of serialization.
- Make it a CI property, at recipe, kernel, and module level, or it will quietly regress.